Why Can’t LLMs Count the R’s in “Strawberry”?
Why LLMs famously miscounted the r’s in strawberry, what tokenization hides from the model, and why newer models get it right.
The Blog
Articles tagged LLM.
Why LLMs famously miscounted the r’s in strawberry, what tokenization hides from the model, and why newer models get it right.
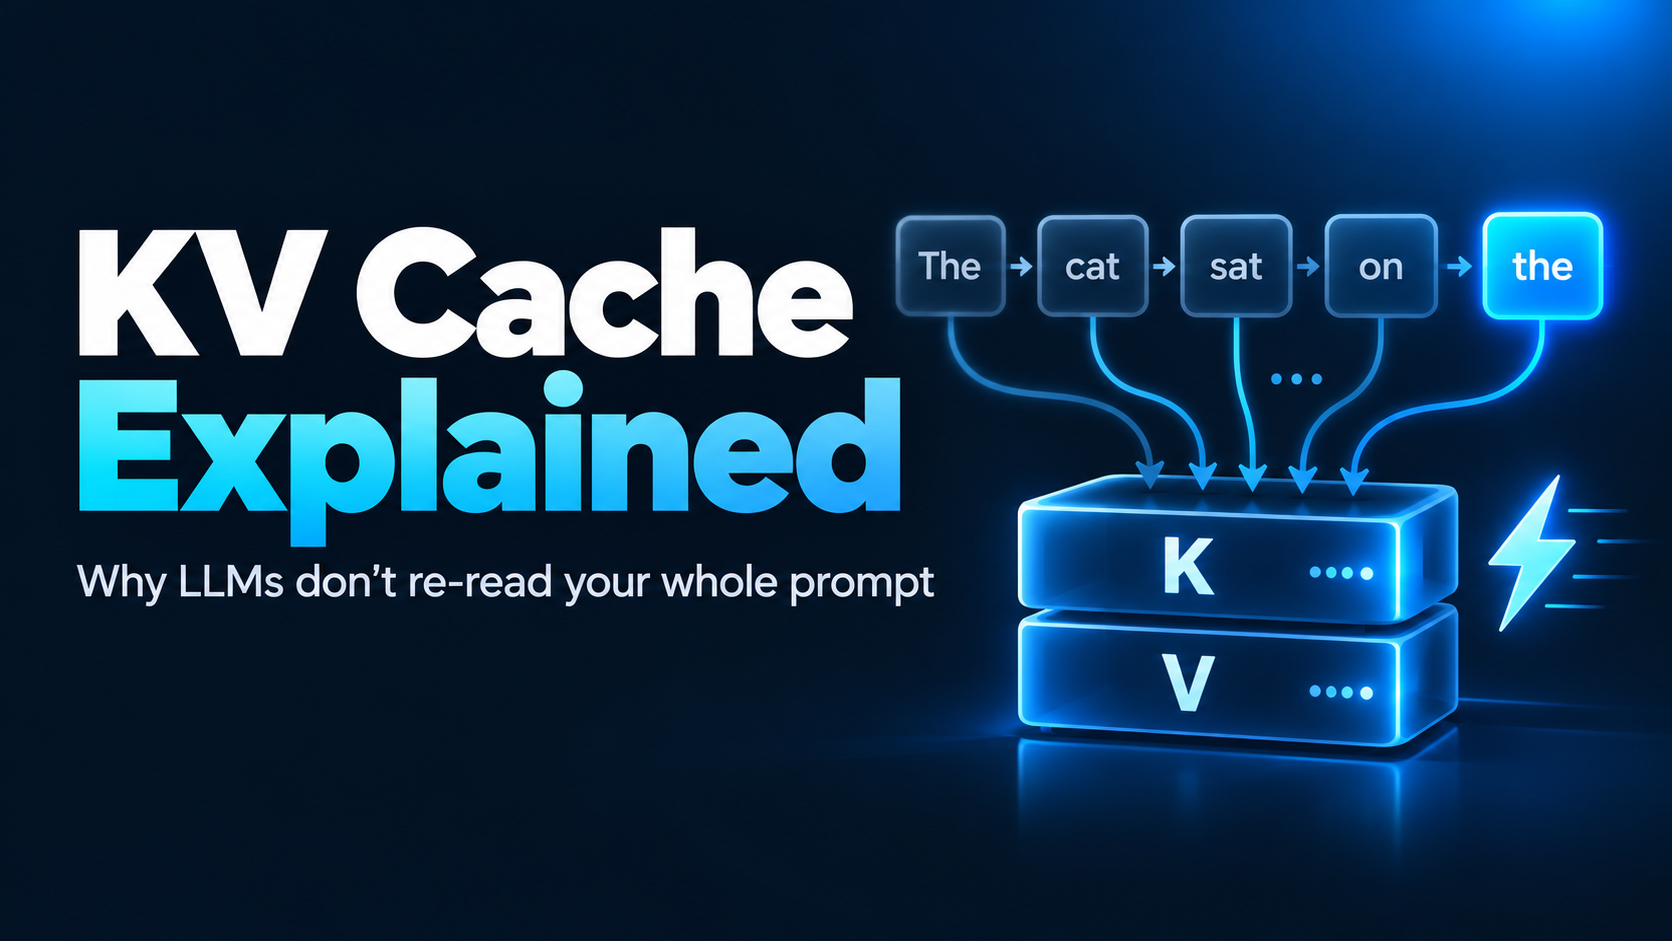
What the KV cache is, why it makes LLMs fast, why the first token is slow, and why long contexts cost so much memory.
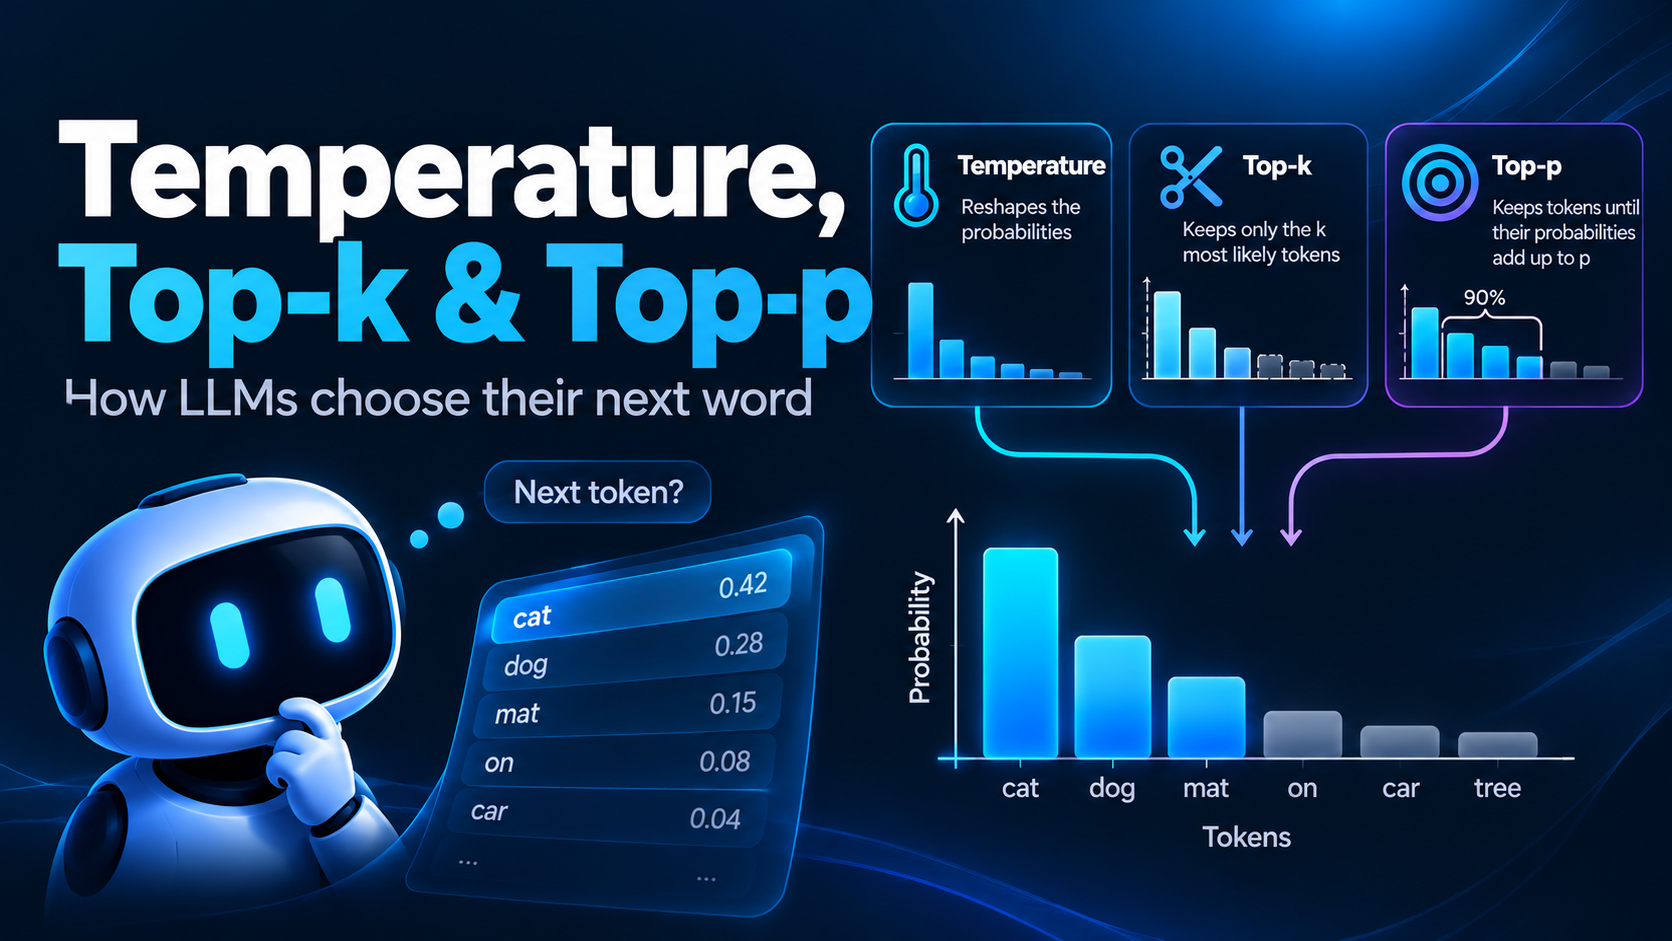
What temperature, top-k and top-p actually do when an LLM picks its next token, how they differ, and which values to use for your tasks.
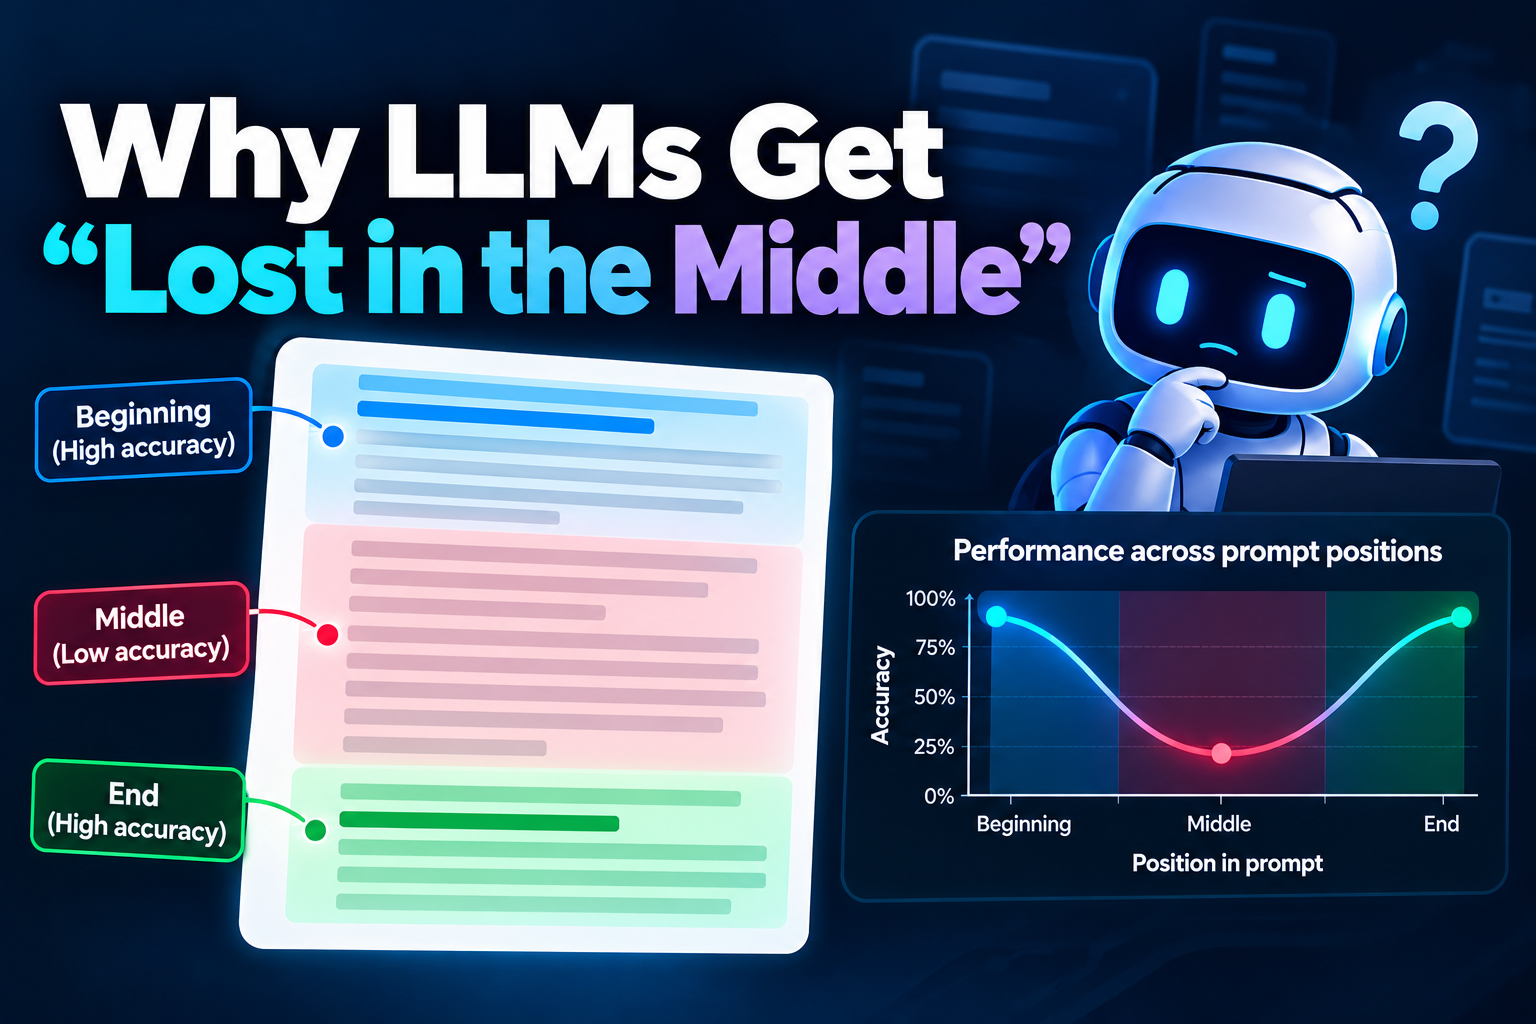
LLMs often perform best when relevant information is at the beginning or end of a long prompt, and struggle when it is buried in the middle. Here is why it happens and how to fix it in your RAG systems.
With the rapid rise of large language models, most of us just build applications that consume third party API, this is so common we even have a word for it, “GPT wrapper”, and honestly, that works fine most of the time. You wire up a model, wrap some code around it, ship it, and everyone’s […]